Blog
Subscribe via RSSDo You Even Need a Decision Model?
A field test of 15 decision models on fresh data: when the new model class pays off, when a simple baseline is enough, and what is left of the marketing.
Is Jev Actually Any Good? A Field Test on Fresh Data
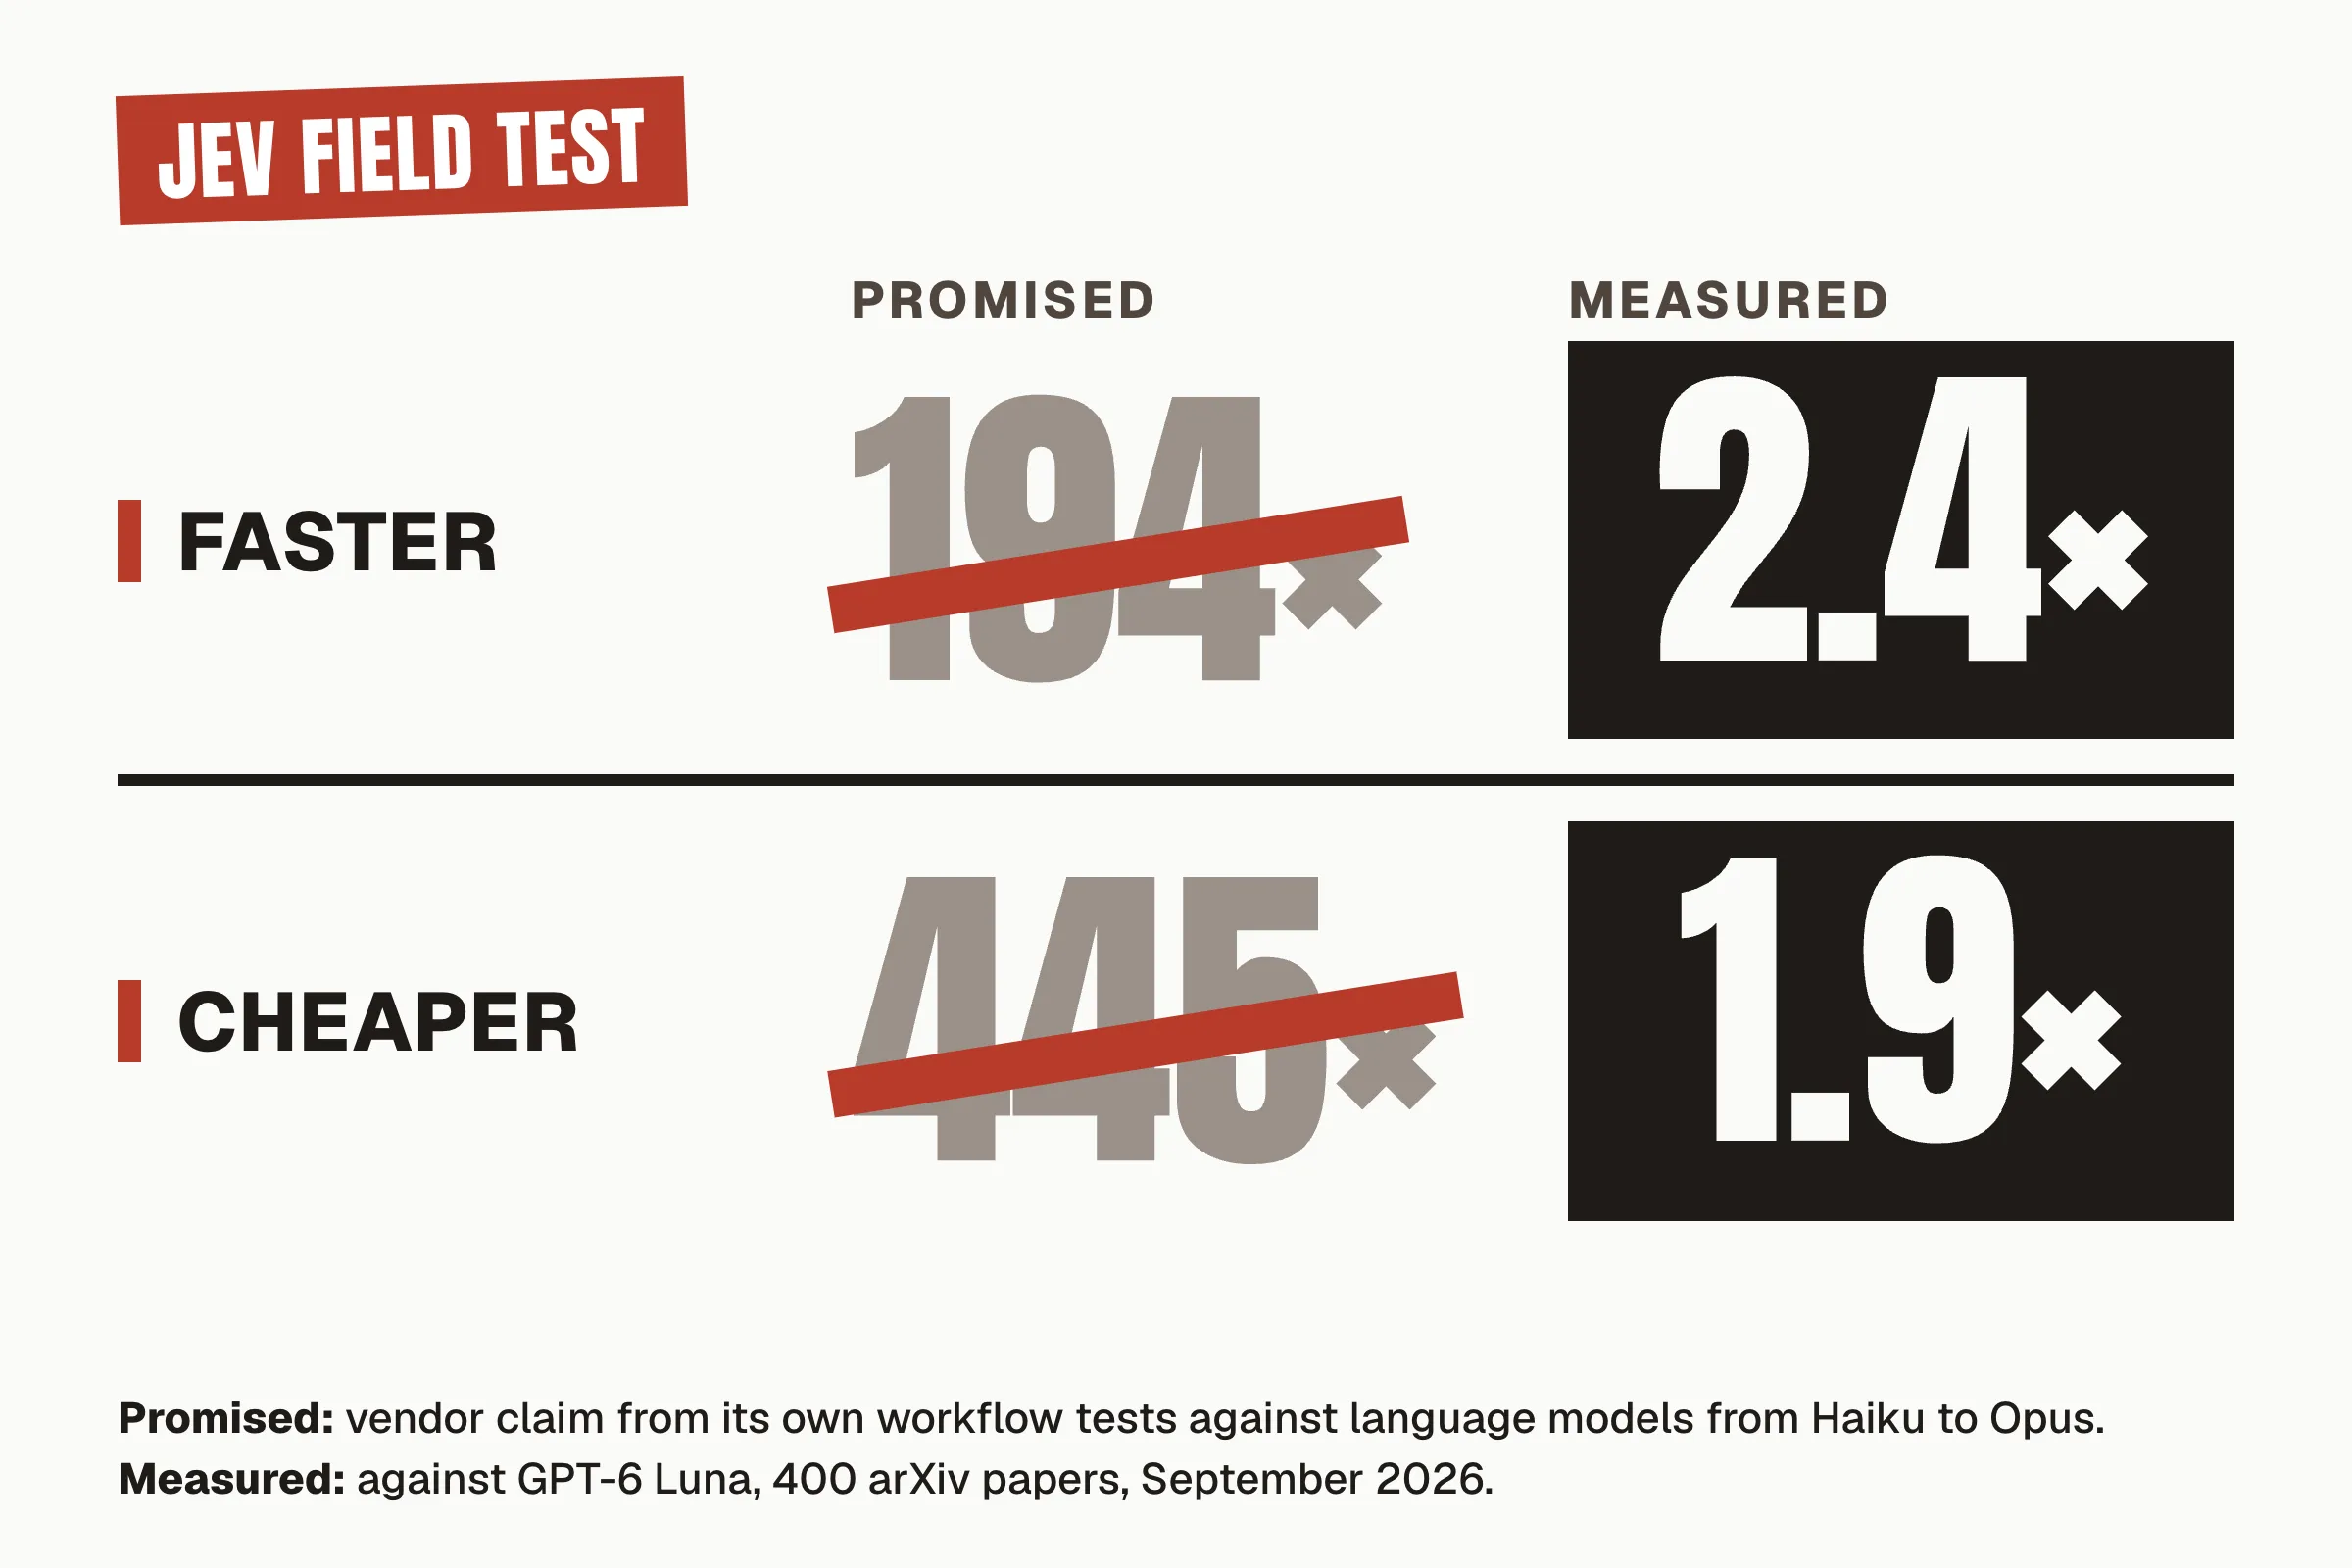
TypeSafe's Jev tested against small LLMs, open alternatives and the old recipe of embeddings plus labels, on fresh data from September 2026.
AI & Rendering | Goals, Revisions, Rules: How to Organize Long-Running Agent Work
How I structured a goal document for overnight agent work, tracked revisions and tasks, and corrected a flawed stopping condition.
AI & Rendering | From a Checked Model to a Good Image: Steering an Agent When You Do Not Know the Craft
My first rendered image got torn apart on LinkedIn. Part 2: how research became the yardstick and why the agent scored its own work too generously.
AI & Rendering | A House Made of Python: From Floor Plan to 3D Scene with a Coding Agent
I had never built a 3D model. A coding agent turned floor plans and open geodata into an editable Blender scene. Part 1: the setup, the checks, the mistakes.
The Painted Guardrail
Why so many different controls are called guardrails, what the metaphor gets wrong, and how to tell what kind of protection you actually have.
Durable Workflows Inside Postgres: A Field Test of pg_durable
A field test of Microsoft's pg_durable: durable workflows inside Postgres, no extra services. Where the bet pays off, and where it bites.
Context Rot: Why Your CLAUDE.md Is Making Your AI Dumber
31,000 tokens of CLAUDE.md instructions before the task even starts. I built a compressor that cut 44% without losing meaning.
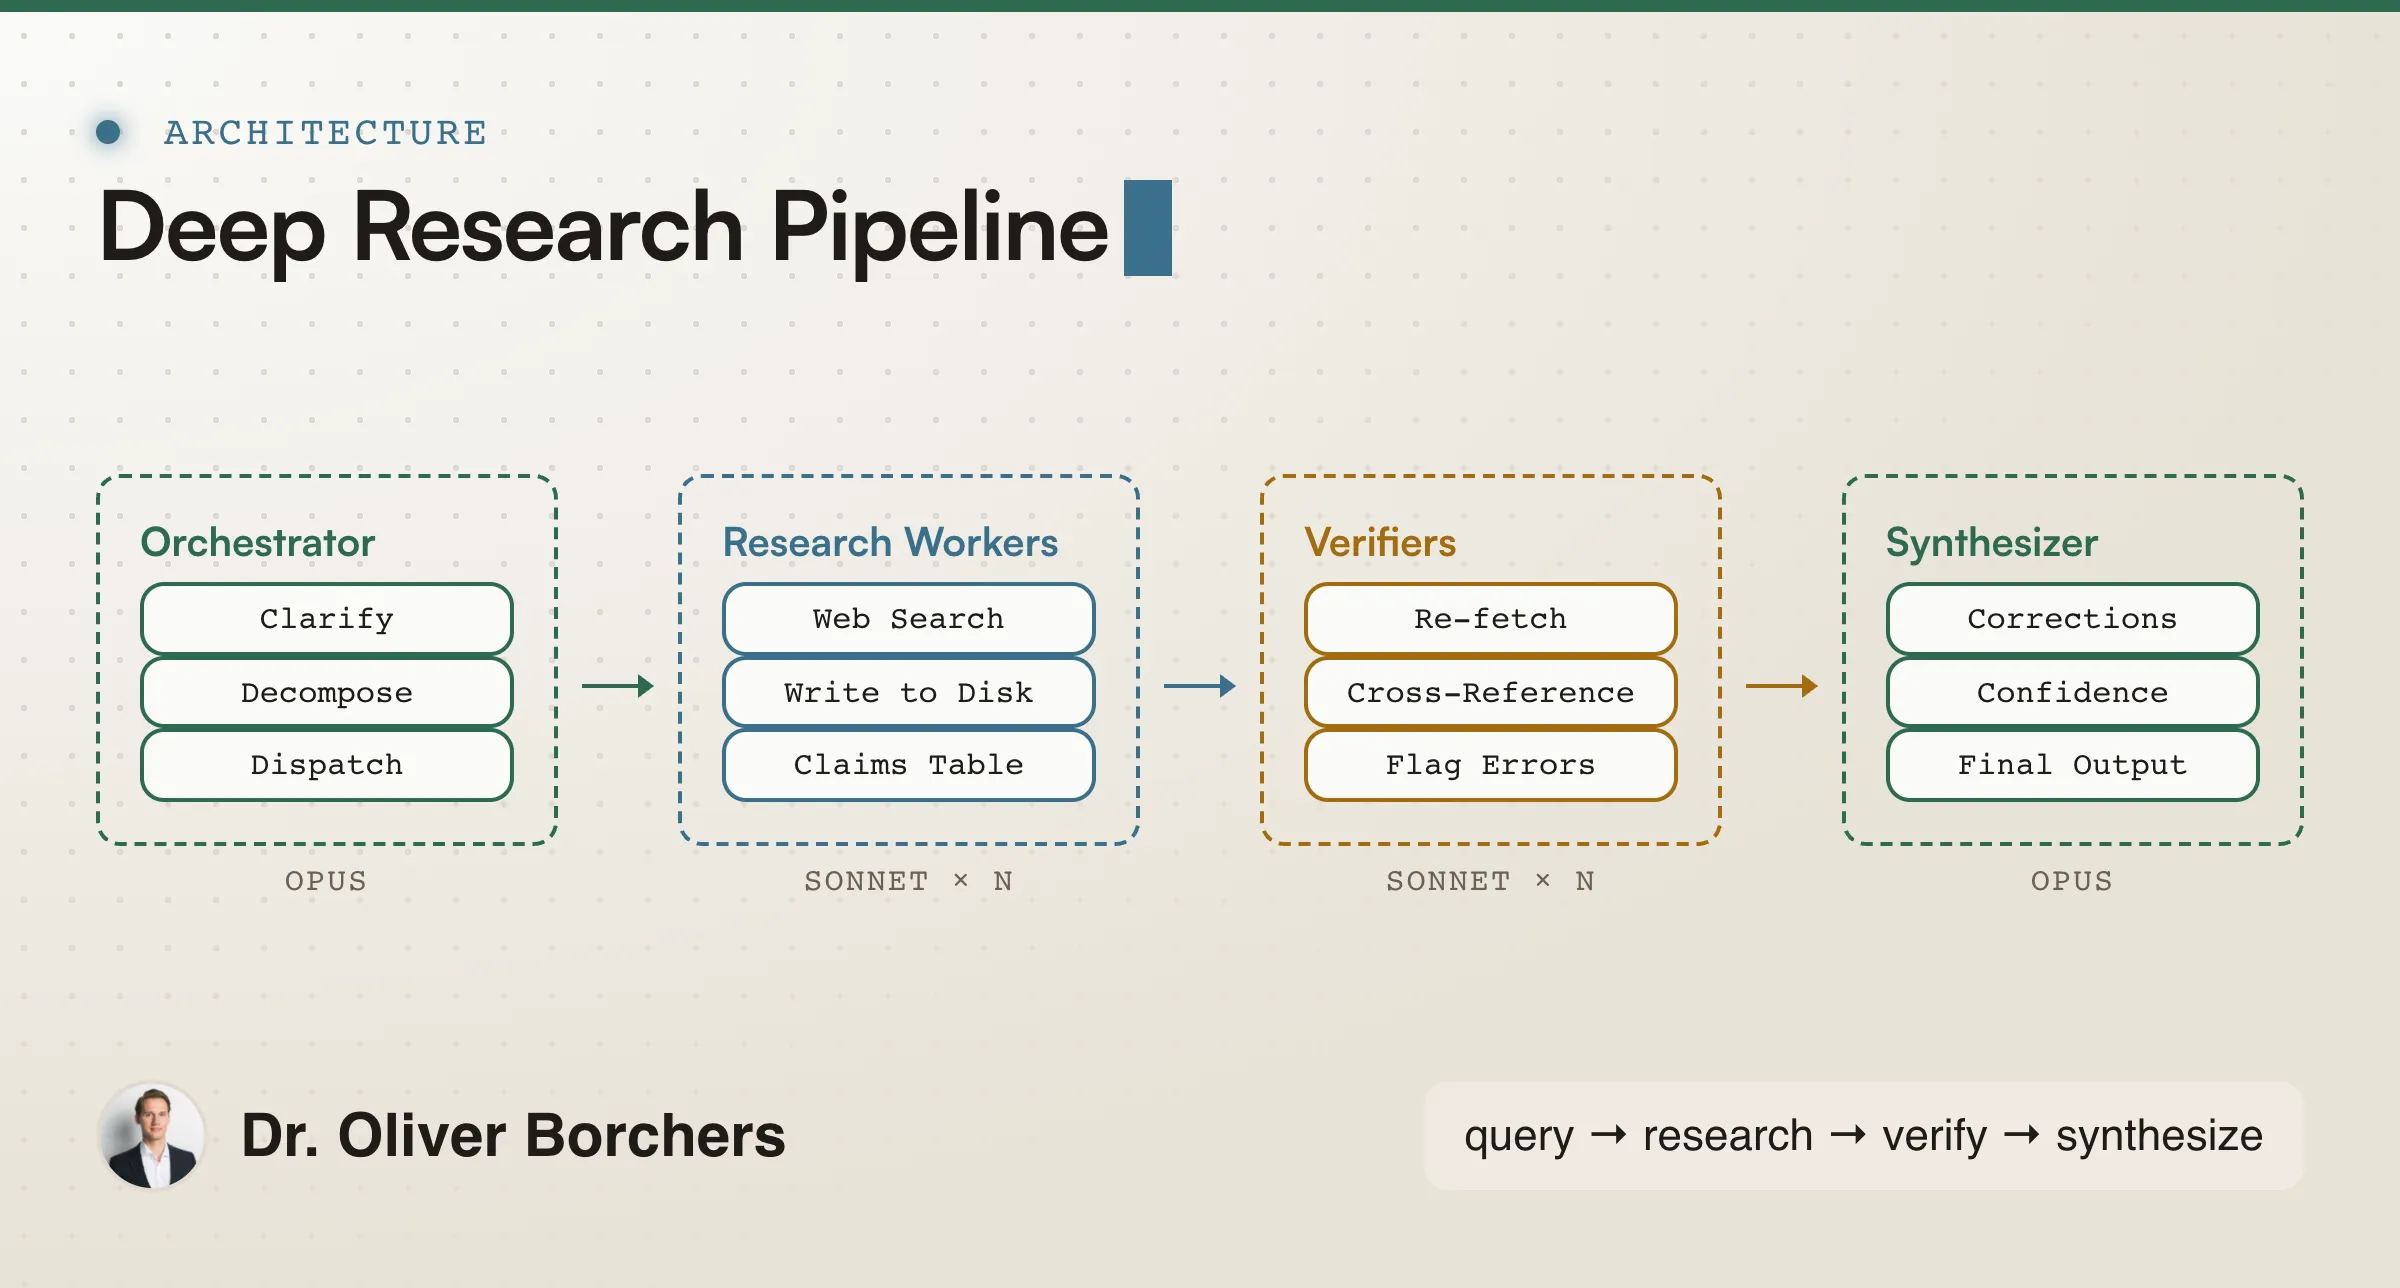
I Taught an AI to Fact-Check Itself. It Lied About That Too.
63 claims checked, 10 wrong, one funding figure fabricated by 11x. Building a deep research plugin and learning what it takes to trust AI output.
I Asked AI to Pick My Brand Colors. It Asked Me Four Questions Instead.
How four parallel brainstorming agents turned a color palette exercise into an identity crisis — and why the questions mattered more than the answers.
The Tool That Wrote This Post
How I built retell, a Claude Code plugin that turns AI conversations into blog posts. Starting from a 14 MB JSONL file with 0.6% signal.
How I Taught Claude to Brainstorm (By Asking It What It Actually Needs)
832 sources, 150 methods, 8 survivors. Building a brainstorming plugin by asking Claude what it actually needs to think better.